介绍
58同城租房网页中,数字是加密的,如下图:
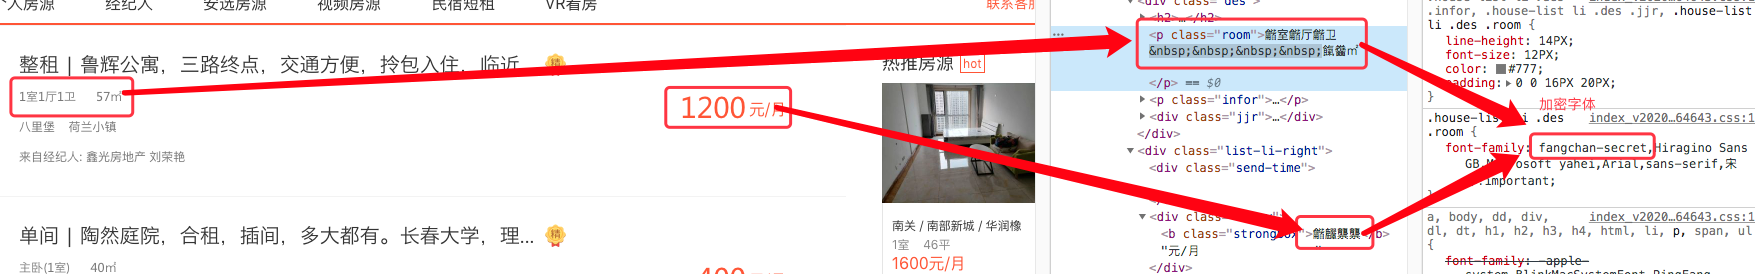
需要破解加密字体
加密字体文件
该加密字体文件,通过base64转码成字符串,包含在该网页的JavaScript代码中,如下图:
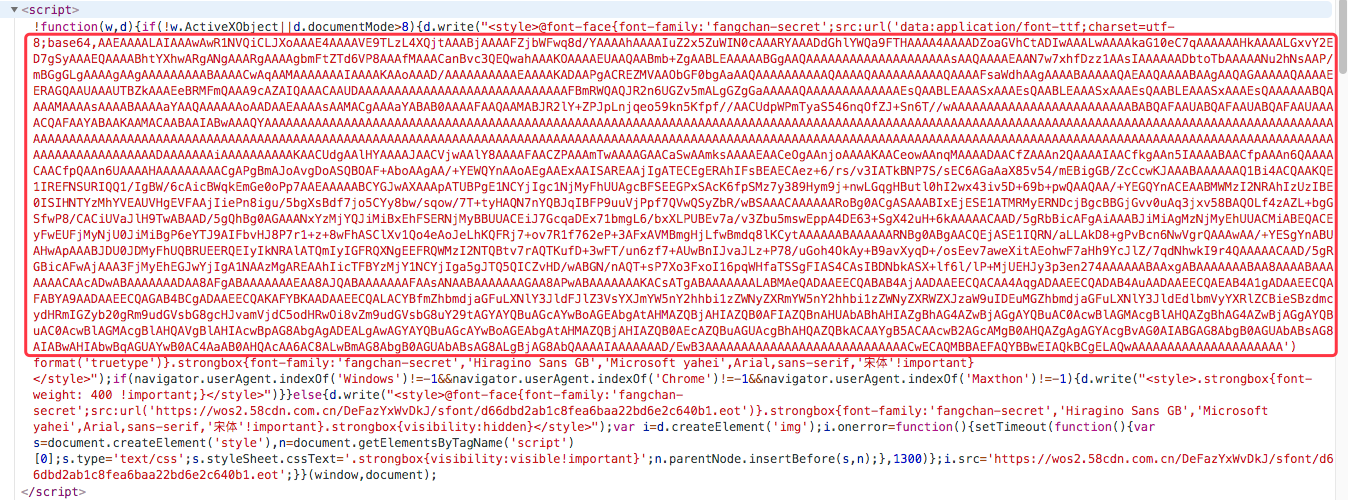
需要截取出该字符串,并做base64转码,成为普通的字体文件
完整代码
import requests,json,base64,io

from bs4 import BeautifulSoup
from io import BytesIO
from fontTools.ttLib import TTFont

headers={
    'user-agent': 'Mozilla/5.0 (Windows NT 6.3; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/70.0.3538.110 Safari/537.36'
    }

url='https://cc.58.com/chuzu/?PGTID=0d100000-0013-f33f-7673-74e19e2b0d2e&ClickID=4'


# 从html中截取base64 字体
def get_font_base64(html):
    start_pos=html.find("base64,")+len("base64,")
    end_pos=html.find("'",start_pos)
    res=html[  start_pos : end_pos ]

    return res

font_map={}

# 将base64格式的字符串进行解码,并读取字体文件信息,将映射关系放入到 font_map 中
def parse_font(font_base64):
    data=base64.b64decode(font_base64)
    # 从内存中加载字体文件
    f = BytesIO(data)
    font=TTFont(f)

    for key,value in font.getBestCmap().items():

        # 截取后2位(因为有10)
        n=int(value[-2:])-1
        # print(key,":",value,":",n)
        font_map[key]=n
    # print(data)

# 翻译,传入加密的数字字符串,返回明文
def decode(s):
    l=[]
    for item in s:
        if item==".":
            l.append(".")
            continue
        a=ord(item)
        # print("s:",s,"--a:",a)
        n=font_map[a]
        l.append(str(n))
    # 将list转换成字符串
    return "".join(l)


with requests.get(url,headers=headers) as resp:
    # 返回的文本内容,html
    # print(resp.text)
    # with open("/Users/mym/Desktop/58.html","wt") as f:
    #     f.write(resp.text)

    font_content=get_font_base64(resp.text)
    # print(font_content)
    parse_font(font_content)

    print(font_map)

    bs=BeautifulSoup(resp.text,"html.parser")
    # css选择器,查找所有的<li class="house-cell">标签
    # select() 返回list类型
    li_tags=bs.select("ul[class='house-list'] li[class='house-cell']")
    print("<li>标签的数量:",len(li_tags))

    for item in li_tags:
        """
        select_one()返回一个对象
        .text:返回标签中的文本内容
        strip():python字符串类中的,作用:去除前后空格
        """
        title=item.select_one("h2").text.strip()

        m=item.select_one("p[class='room']").text.strip()
        m=m[m.find(" "):-1].strip()

        # print(title,m,end=",")
        m2=decode(m)

        price=item.select_one("b[class='strongbox']").text.strip()
        price2=decode(price)
        print(title,",面积明文:",m2,",价格:",price2)